Latest News

  • Research Highlights

  • Publish Date:2026-08-13
NYCU Research Team Earns Second Consecutive ISCA Acceptance with Energy-Efficient AI Breakthrough
NYCU Joins Taiwan’s First High School–University–Research Alliance to Cultivate Future Scientists
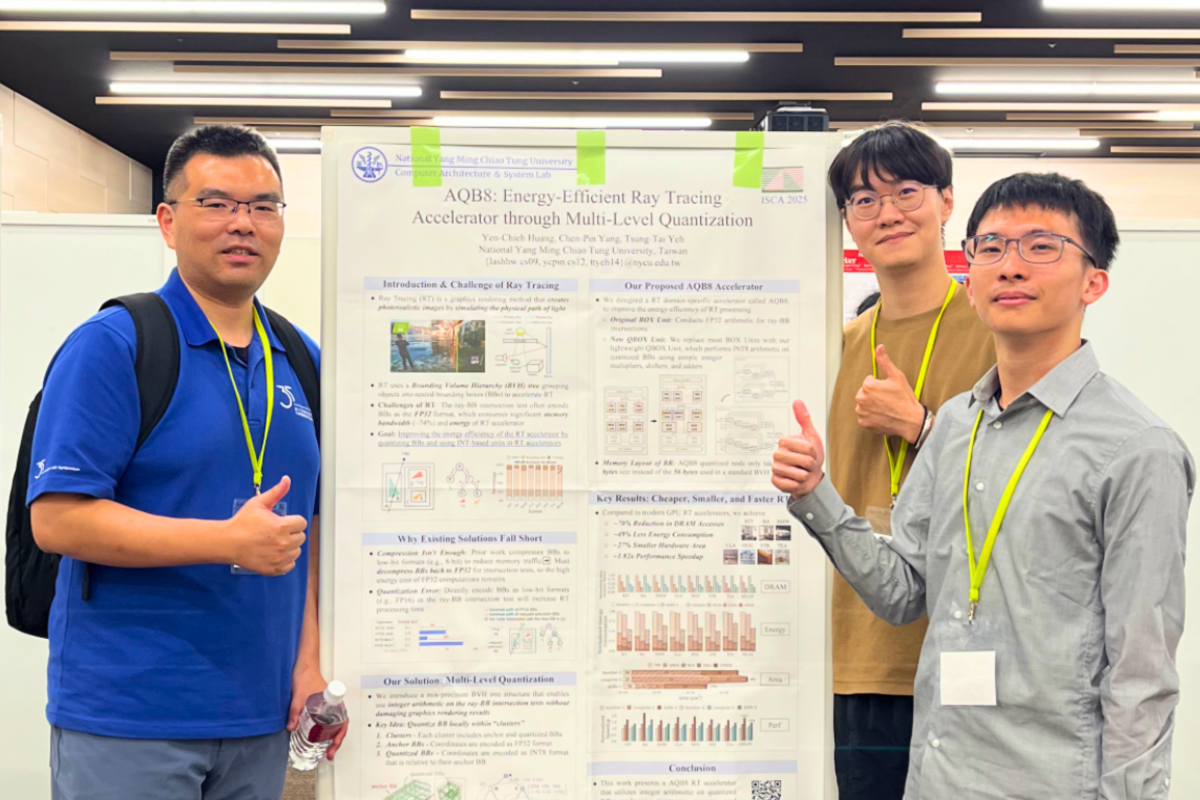
Professor Tsung-Tai Yeh (left) and members of NYCU’s Computer Architecture and System Lab at the ISCA 2025 poster session
 
Edited by Chance Lai
______
In computer science, the International Symposium on Computer Architecture (ISCA) is often described as the “Olympics of computer architecture.” Known for its highly selective review process, ISCA showcases some of the world’s most forward-looking advances in hardware design and chip architecture. Taiwan’s presence at the conference has remained limited over the past decade, averaging fewer than one paper per year. Yet a research team led by Professor Tsung-Tai Yeh of the Department of Computer Science at National Yang Ming Chiao Tung University (NYCU) has now secured acceptances for two consecutive years.

Professor Yeh’s team will return to ISCA in 2026 with its Omni-LUT research, following the team’s presentation of AQB8 at ISCA 2025. Together, the two studies address two major challenges facing the technology industry: the soaring memory demands of AI and the high power consumption of high-fidelity graphics.

Solving the Data-Movement Bottleneck

One of the industry’s biggest bottlenecks is the sheer volume of data that modern computing workloads must move. Professor Yeh explains that both large language models (LLMs) and ultra-realistic 3D rendering rely on frequent transfers of enormous amounts of data between processors and memory.

Like vehicles caught in a traffic jam, these transfers consume substantial time and energy, slowing systems and generating heat. Reducing data movement without sacrificing accuracy has therefore become a key priority for the semiconductor and AI industries.

Omni-LUT: Redefining Long-Context AI

Through Omni-LUT, the team is pushing the boundaries of long-context processing for LLMs. Microsoft Research previously proposed using lookup tables (LUTs) with ultra-low-precision quantization to replace conventional computations and reduce the hardware footprint. However, the technology faced difficulties in quantizing the key-value (KV) cache.

Because the KV cache is generated dynamically during model inference, it cannot be easily preprocessed. Its memory requirements also grow rapidly as context length increases, particularly when models handle very long documents.


Professor Yeh’s team developed a new quantization mechanism—different from Google's approach—that integrates seamlessly with LUT accelerators. The breakthrough significantly eases the memory pressure created by the KV cache, enabling long-context AI workloads to run faster and more reliably on conventional hardware.

AQB8: Cinematic Graphics with Lower Power Consumption

In 3D rendering, ray tracing produces lifelike visuals by simulating the paths of countless light rays. However, the process requires intensive computation and frequent data transfers. Even today’s most powerful graphics cards can struggle with such workloads.

With AQB8, Professor Yeh’s team departed from conventional high-precision computing frameworks. The team developed an algorithm that represents data at lower precision with virtually no loss in visual quality. By sharply reducing data movement, AQB8 could enable mobile devices to render cinematic-quality graphics while consuming less power.

The work attracted considerable interest from leading global chipmakers last year because of its potential to reduce energy use without sacrificing visual fidelity.

Future Horizons: From Quantum Computing to Cybersecurity

Professor Yeh is now extending the team’s two core research areas—ray-tracing accelerator architecture and hardware-aware quantized compression—to new applications. The team is adapting ray-tracing techniques for quantum circuit simulation while applying memory-compression methods to information security.

A related project by the team received a 2025 Qualcomm Innovation Fellowship in East Asia. The project uses quantization-based compression to improve the efficiency of homomorphic encryption, potentially allowing AI systems to process encrypted data rapidly while preserving privacy.

With papers presented at ISCA in consecutive years, the NYCU team has demonstrated that Taiwan’s strengths extend beyond world-class semiconductor manufacturing to the hardware-software co-design expertise needed to shape the future of AI, quantum computing, and cybersecurity.
 
文圖/資訊人院刊
在計算機科學界,有一座被譽為「電腦架構奧林匹克」的聖殿——ISCA(國際電腦架構交談會)。這項會議的入選門檻極高,代表了全球硬體設計與晶片架構的最前瞻思維。過去十年,整個台灣在該會議的發表量寥寥可數,平均一年不到一篇。然而,這項學術天花板,在近兩年被陽明交通大學資訊工程系葉宗泰教授的研究團隊連續打破。

葉宗泰老師團隊憑藉 Omni-LUT 研究再次挺進 ISCA 2026,這不僅是該團隊連續第二年插旗這座聖殿,更是在機器人頂級會議 ICRA 同時發表了突破性成果。這項成就背後,關鍵在於這兩篇論文分別解決了當前科技界最頭痛的兩個問題:「AI 太吃記憶體」與「高畫質運算太耗電」。

產業界當前最頭痛的痛點是資料搬移量過大導致的運算瓶頸。葉教授深入淺出地指出,無論是當紅的大語言模型(LLM)還是追求極致真實的 3D 影像渲染技術,核心難題都在於必須頻繁地在晶片與記憶體之間搬動龐大資料。這就像交通堵塞一樣,耗費了絕大部分的電力與時間,導致運算又慢又發燙。因此,如何「搬動更少的資料」卻能達到同樣精準的結果,成為未來半導體與 AI 產業最關鍵的技術轉型方向,這也是當前全球科技巨頭都在競爭的技術制高點。

在針對大語言模型的 Omni-LUT 研究中,團隊挑戰了當前長文本處理的極限。雖然先前 Microsoft Research 已提出利用「查表法」(Look-up Table)搭配超低精度量化來取代傳統計算,藉此縮減晶片面積,但該技術尚未能解決「KV Cache」的量化難題。由於 KV Cache 是在模型執行時動態生成的,難以預先處理,導致在面對超長文件時,記憶體需求仍會急劇攀升。葉老師團隊針對這一缺口,研發出與 Google 策略不同、且能與查表加速器完美契合的新型量化機制,並改良了硬體架構。這項突破讓 AI 在處理超長文本時,能大幅降低 KV Cache 對記憶體的壓迫,讓長文本運算在常規硬體上跑得更快、更穩。
 

而在 3D 影像渲染領域,光線追蹤技術雖然能生成逼真影像,卻因需要模擬海量光線並頻繁搬移資料,即便是當前市面上最高階的顯示卡運算起來也相當吃力。葉老師團隊研發出的 AQB8 技術,突破了業界過去習慣的高精度計算框架,找到了一套全新的算法,能將資料大幅降至低精度卻幾乎不失真。這項技術透過大幅減少資料搬移量,讓行動裝置也能以低功耗跑出電影等級的細緻畫面,去年在國際展示時更吸引了多家晶片大廠的高度關注,驚訝於這項能顯著降低功耗且不影響影像品質的新型算法。

展望未來,葉宗泰老師正積極將這兩項核心技術——「光線追蹤加速架構」與「硬體感知量化壓縮」——推向更寬廣的應用領域。團隊目前嘗試將光線追蹤的加速邏輯轉化為量子電腦電路模擬的利器,並同步將記憶體壓縮技術投入資訊安全領域。葉老師與Qualcomm合作的創新計畫已榮獲 2025 Qualcomm Innovation Fellowship in East Asia ,其目標是利用量化壓縮特性優化「同態加密」的運算效率,讓 AI 在處理加密資料時,既能保證隱私不外洩,又能維持極高的運算速度。連續兩年插旗 ISCA,證明了台灣團隊不僅具備世界級的晶片製造實力,更有能力在「軟硬體協同設計」上定義未來的算力規則,並將這套節能高效的架構推展至量子運算與數位安全等更多元的應用場景。
 

Related Image(s):