Latest News

  • Honor

  • Publish Date:2026-08-18
NYCU Team Takes Second Place at SemEval with AI System Detecting Online Polarization in 22 Languages
 
Edited by Chance Lai
______
Social media algorithms make it easier for users to find content that matches their interests. But that convenience can also keep people trapped in echo chambers, while emotionally charged posts — often rewarded with greater attention — push online conversations toward increasingly polarized extremes.

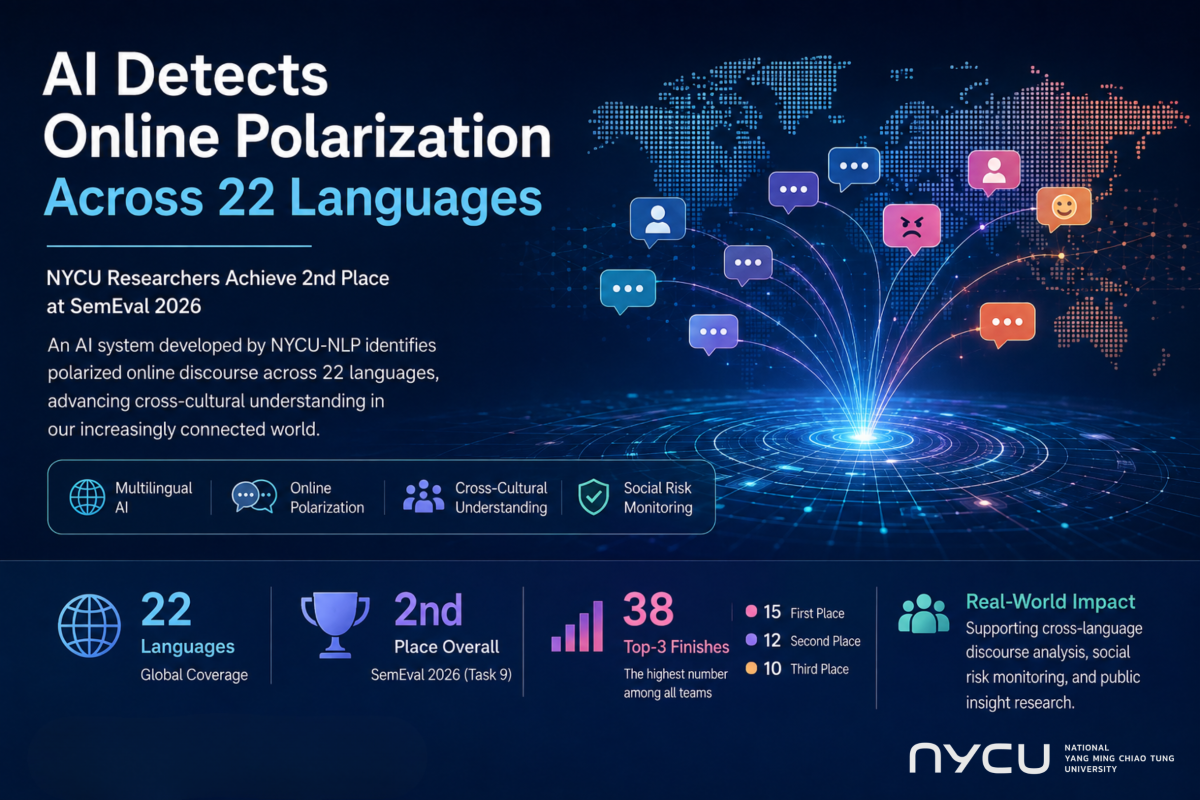
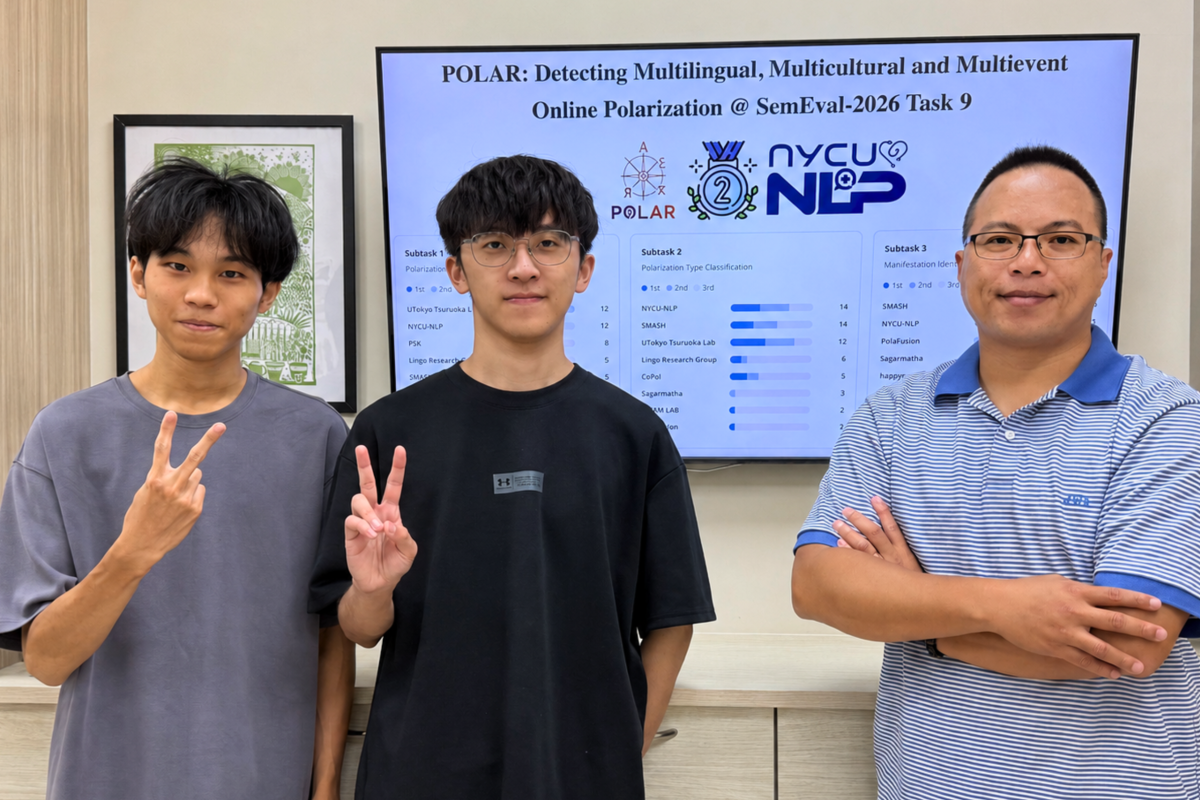
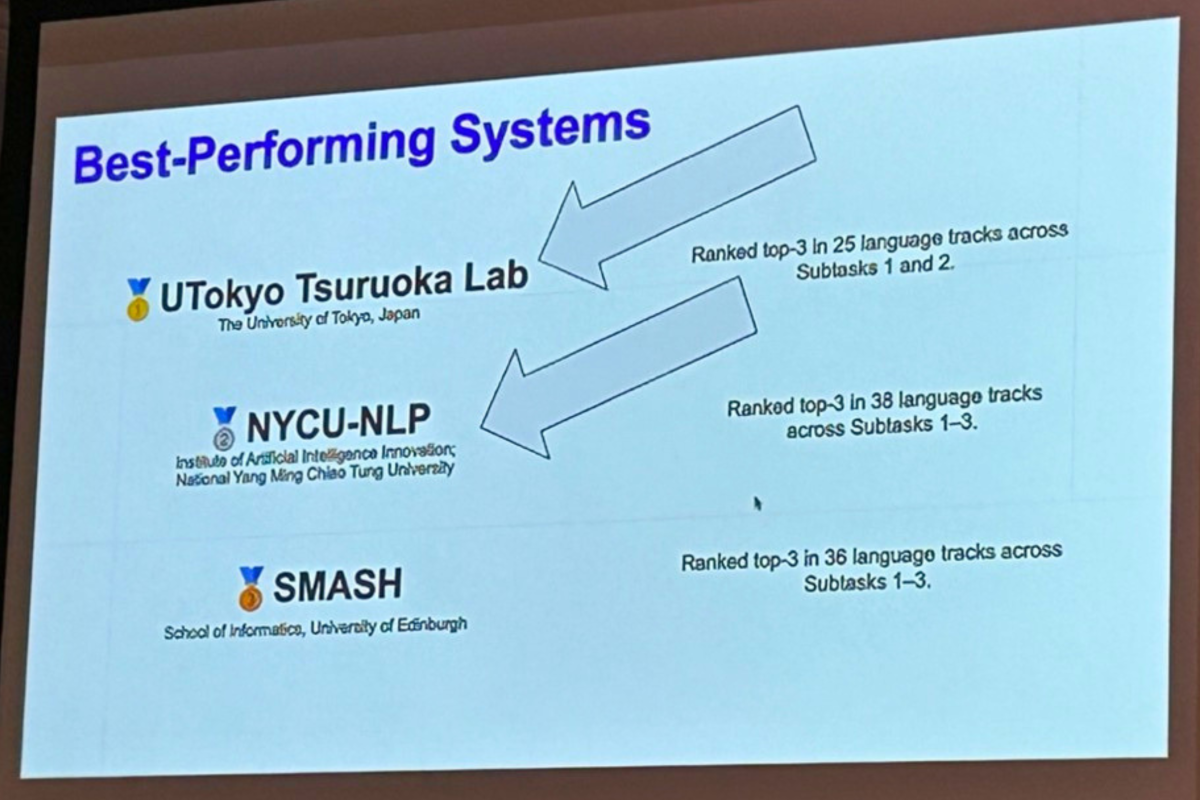
A research team at National Yang Ming Chiao Tung University (NYCU), led by Lung-Hao Lee, an associate professor at NYCU’s Institute of Intelligent Systems, has developed an artificial intelligence system capable of identifying polarized online discourse across 22 languages. The NYCU-NLP team, which also included master’s students Ding-Xiang Lin and Po-Chun Chu, placed second overall in Task 9 at SemEval 2026, behind a team from the University of Tokyo.
 
From left: Po-Chun Chu, Ding-Xiang Lin and Associate Professor Lung-Hao Lee of NYCU’s Institute of Intelligent Systems.

A Global Challenge Spanning 22 Languages

SemEval, the International Workshop on Semantic Evaluation, is one of the natural language processing field’s leading international evaluation forums. Task 9 this year focused on detecting multilingual, multicultural and multievent online polarization.

The challenge required AI systems to determine whether online content was polarized, identify the type of polarization involved and recognize how that polarization was expressed. The evaluation covered 22 languages, including Chinese, English, German, Spanish, Arabic, and Burmese, and drew participants from universities and research institutions worldwide.

Some of the languages included in the competition are considered low-resource languages because they have relatively small speaker populations or limited amounts of digital data available for training AI systems. “The challenge is not only the limited training data,” Lee said. “Political, cultural and social contexts also vary considerably from one country and event to another, making it much more difficult for AI to interpret the content accurately.”

Rather than optimizing its system for a single language or one specific subtask, the NYCU team set out to develop a broadly applicable method that could deliver reliable performance across languages and assignments.


Three AI Models Working as One

During development, the researchers compared 10 recently released open-weight language models. Based on their experiments, they selected Google’s Gemma 3, Mistral Small 3.2 from the French AI company Mistral AI and Microsoft’s Phi-4. The team then combined the three models using a technique known as model stacking. The approach integrates predictions from multiple models, much like bringing together specialists with different strengths to solve the same problem.

By allowing the models to complement one another, the system achieved greater consistency across languages and different types of polarization analysis. It delivered particularly strong results in Chinese, Spanish and German, helping NYCU secure second place overall.

The system recorded 38 top-three finishes across the competition’s language-specific evaluations — the highest number achieved by any participating team. It placed first in 15 evaluations, second in 12 and third in 10.

From Competition Results to Real-world Applications

Lee said online polarization can leave users with one-sided information, deepen divisions between social groups and shrink the space available for reasoned public debate. “Online polarization has become an important new area of international natural language processing research,” he said. “The technology could eventually support cross-language analysis of online discourse, social risk monitoring and research into public issues.”

Such systems could help researchers and public institutions better understand how online divisions emerge across different cultures, languages and major events — and provide a clearer view of the forces shaping public debate in an increasingly connected world.

A presentation slide lists NYCU-NLP as the competition’s second-best-performing system, behind the University of Tokyo’s Tsuruoka Laboratory.A presentation slide lists NYCU-NLP as the competition’s second-best-performing system, behind the University of Tokyo’s Tsuruoka Laboratory.
文/公關組 照片/研究團隊
資訊圖/國際宣傳辦公室


演算法推薦讓社群媒體使用者更有效率地接收感興趣的資訊,卻也使人長期置身資訊同溫層;情緒化言論因更容易獲得關注,使網路討論逐漸走向兩極化發展。

由智能系統研究所李龍豪副教授領軍的自然語言處理研究團隊(NYCU-NLP)成員林鼎翔、褚柏均運用三個開源大型語言模型,開發出可辨識22種語言的網路極化言論模型,這套模型在國際語意評測競賽任務9奪下第二名佳績,第一名為日本東京大學。

SemEval是自然語言處理領域重要的國際語意評測競賽,今年任務9主題是網路極性言論分析,聚焦多語言、多文化及不同事件下的網路極化現象,涵蓋中文、英文、德文、西班牙文、阿拉伯文及緬甸文等22種語言,吸引多所國際知名大學參賽。

李龍豪表示,部分參賽語言屬於使用人口或數位資料較少的低資源語言,不僅可供模型學習的資料有限,不同國家、文化及事件脈絡也各有差異,增加AI判讀的難度。因此,團隊的策略並非只追求特定語言或單項任務的最佳成績,而是尋找能適用不同語言及任務、維持穩定表現的通用方法。


在開發過程中,團隊比較了10個近期表現較佳的開源大型語言模型,最後依據實驗結果,選用Google釋出的Gemma-3、法國AI新創公司Mistral AI開發的Mistral-small-3.2,以及微軟釋出的Phi-4。透過模型堆疊方式整合判斷結果,如同讓具備不同專長的成員共同解題,提升系統面對多語言及多類型任務時的整體穩定性。最終團隊在中文、西班牙文及德文等語言項目表現尤其突出,整體成績排名第二。

李龍豪指出,網路極化可能使民眾接收到片面資訊,加劇社會群體對立,壓縮理性討論空間,已成為國際自然語言處理研究的新課題。相關技術未來可應用於跨語言網路輿情分析、社群風險觀測及公共議題研究,協助掌握不同文化與事件中的網路對立現象。

Related Image(s):